Illustrative reenactment - not a recorded Copilot session. Test results are real fixture runs.
Client: VS Code / Copilot app | mattpocock/skills. Track: skills.
Commands: /grill-me.
The dialogue and artifact snapshots below are authored examples. Test summaries are verbatim excerpts from real fixture runs; stack traces and machine-local paths are omitted.
Step 1: Invoke /grill-me
Participant:
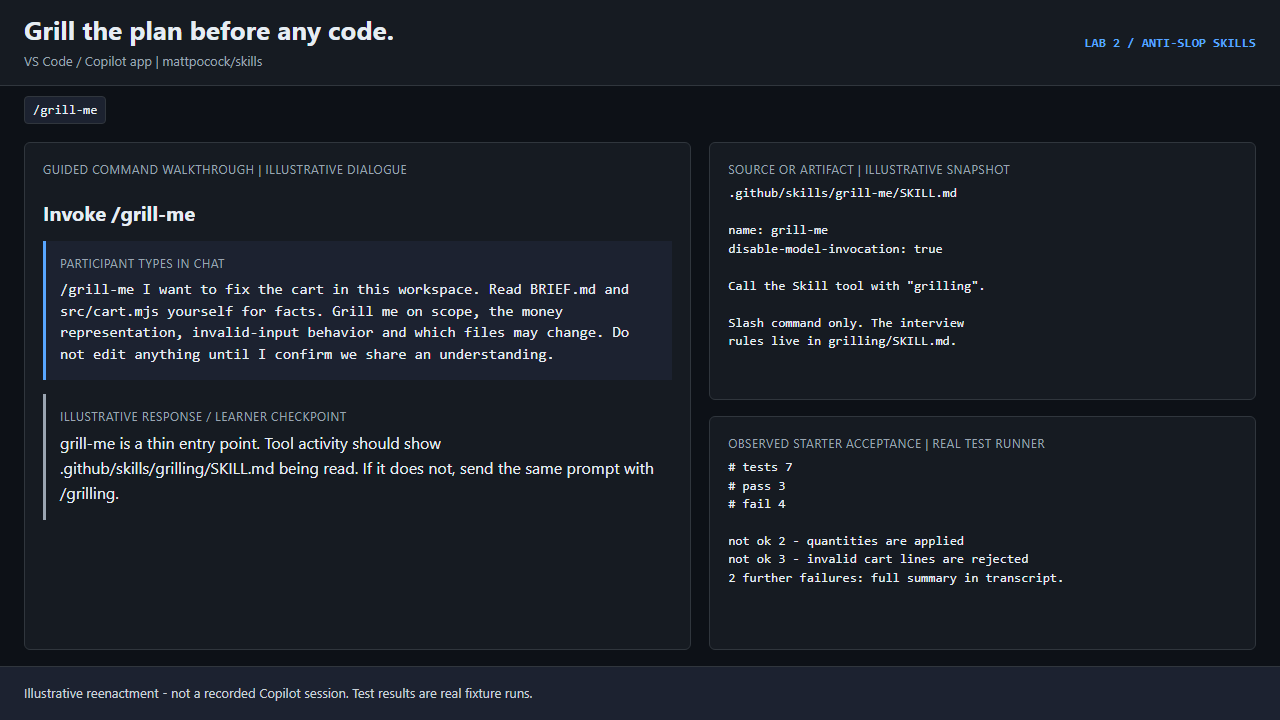
/grill-me I want to fix the cart in this workspace. Read BRIEF.md and src/cart.mjs yourself for facts. Grill me on scope, the money representation, invalid-input behavior and which files may change. Do not edit anything until I confirm we share an understanding.
Illustrative checkpoint:
grill-me is a thin entry point. Tool activity should show .github/skills/grilling/SKILL.md being read. If it does not, send the same prompt with /grilling.
Source or artifact snapshot:
.github/skills/grill-me/SKILL.md

name: grill-me
disable-model-invocation: true

Call the Skill tool with "grilling".

Slash command only. The interview
rules live in grilling/SKILL.md.
Observed test summary:
ok 1 - existing cart behavior is preserved
not ok 2 - quantities are applied
not ok 3 - invalid cart lines are rejected
not ok 4 - safe integer cents are enforced
ok 5 - inputs are left untouched
ok 6 - public API and scope are preserved
not ok 7 - learner regressions catch the original bug
# tests 7
# suites 0
# pass 3
# fail 4
# cancelled 0
# skipped 0
# todo 0
Step 2: Answer one round of numbered questions
Participant:
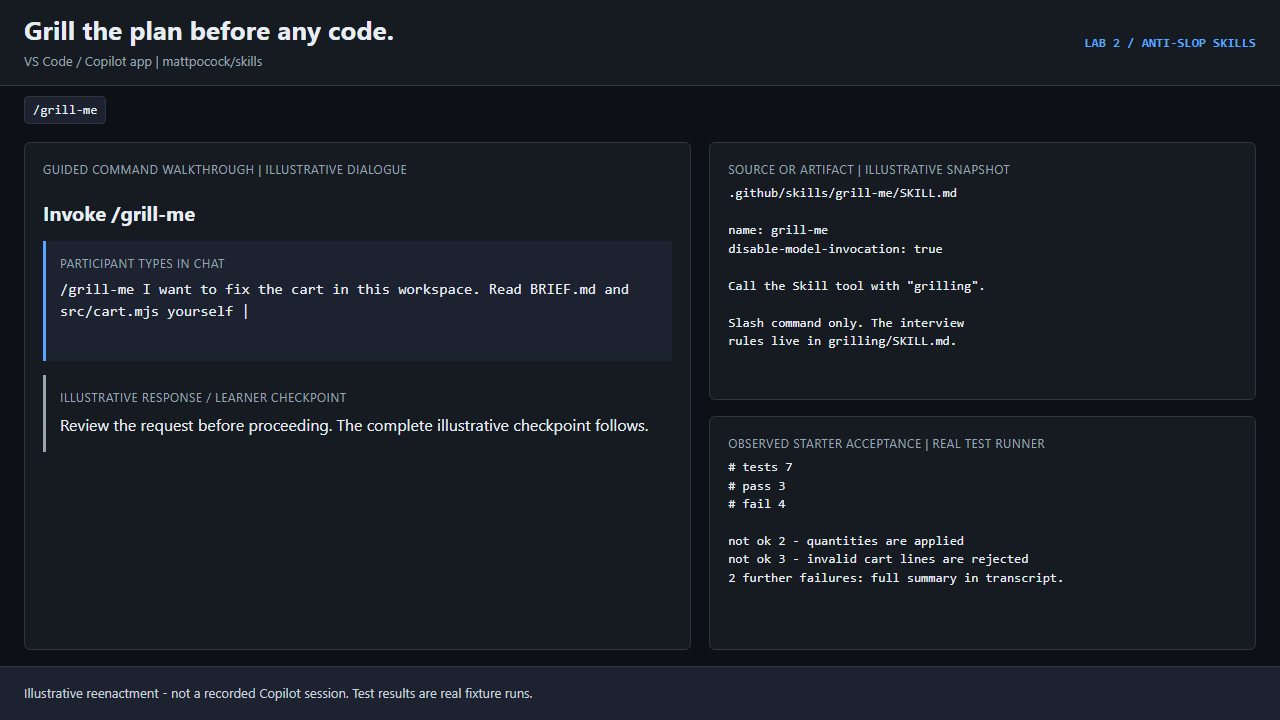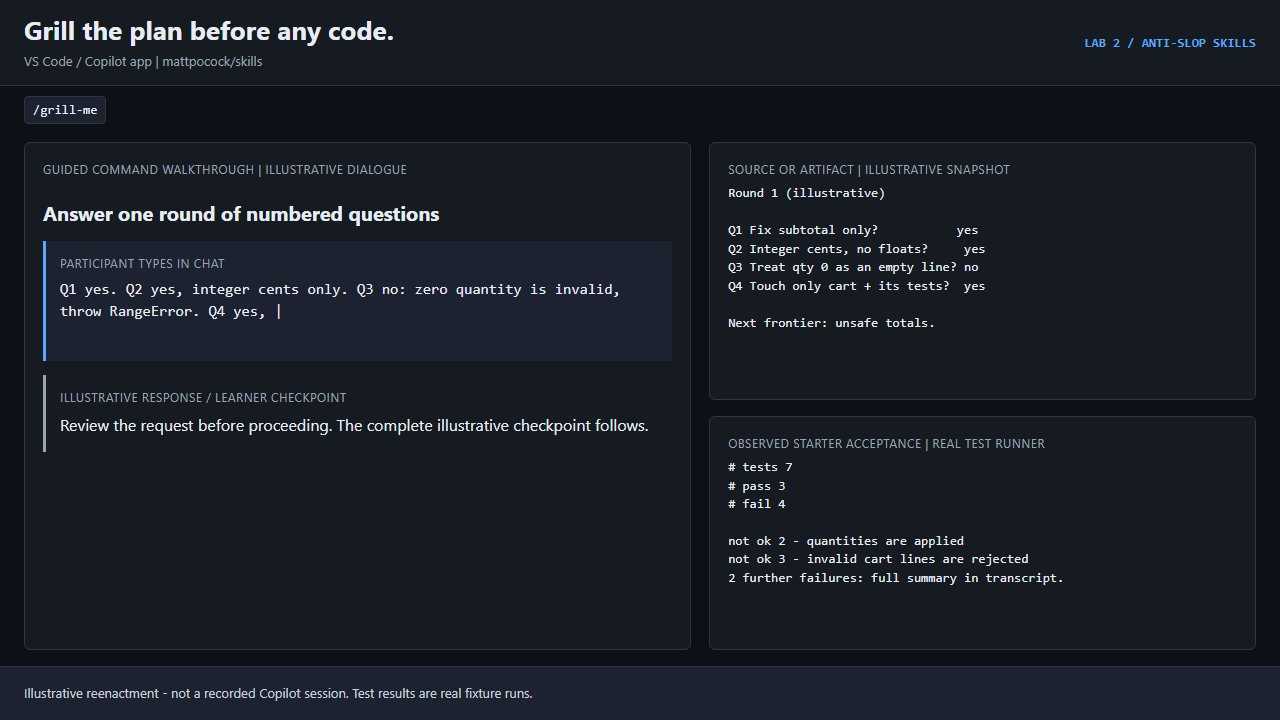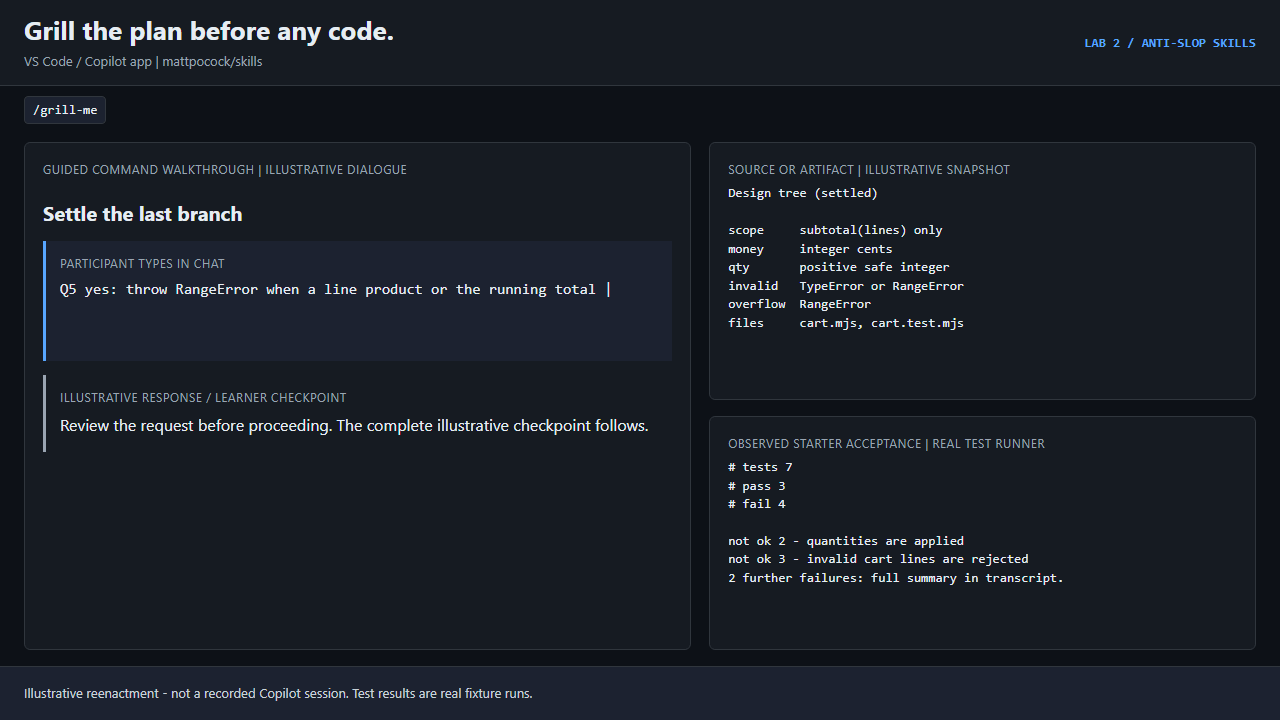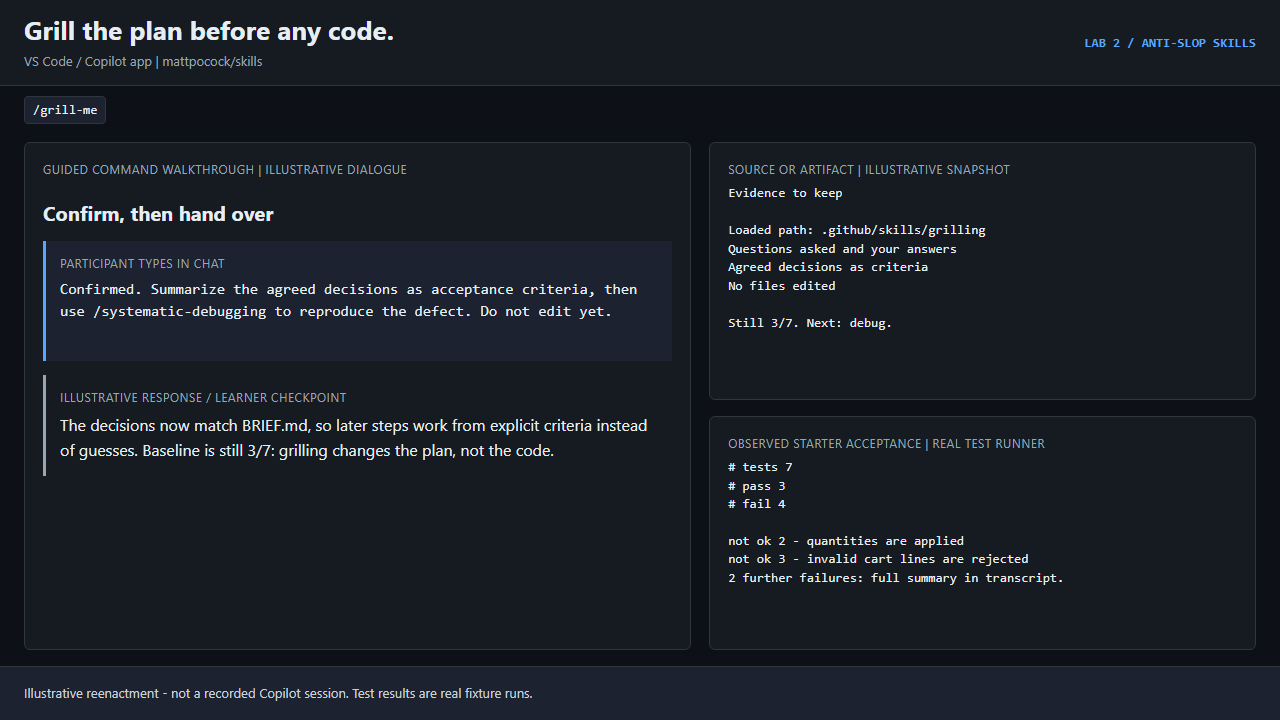
Q1 yes. Q2 yes, integer cents only. Q3 no: zero quantity is invalid, throw RangeError. Q4 yes, only src/cart.mjs and src/cart.test.mjs.
Illustrative checkpoint:
Each question arrives with a recommended answer, so "yes" accepts it. Facts such as the current reducer are looked up in BRIEF.md and the code, not asked of you.
Source or artifact snapshot:
Round 1 (illustrative)

Q1 Fix subtotal only?           yes
Q2 Integer cents, no floats?     yes
Q3 Treat qty 0 as an empty line? no
Q4 Touch only cart + its tests?  yes

Next frontier: unsafe totals.
Observed test summary:
ok 1 - existing cart behavior is preserved
not ok 2 - quantities are applied
not ok 3 - invalid cart lines are rejected
not ok 4 - safe integer cents are enforced
ok 5 - inputs are left untouched
ok 6 - public API and scope are preserved
not ok 7 - learner regressions catch the original bug
# tests 7
# suites 0
# pass 3
# fail 4
# cancelled 0
# skipped 0
# todo 0
Step 3: Settle the last branch
Participant:
Q5 yes: throw RangeError when a line product or the running total is no longer a safe integer.
Illustrative checkpoint:
The session ends when every branch of the design tree has an answer. Nothing has been edited; the agent waits for you to confirm the shared understanding.
Source or artifact snapshot:
Design tree (settled)

scope     subtotal(lines) only
money     integer cents
qty       positive safe integer
invalid   TypeError or RangeError
overflow  RangeError
files     cart.mjs, cart.test.mjs
Observed test summary:
ok 1 - existing cart behavior is preserved
not ok 2 - quantities are applied
not ok 3 - invalid cart lines are rejected
not ok 4 - safe integer cents are enforced
ok 5 - inputs are left untouched
ok 6 - public API and scope are preserved
not ok 7 - learner regressions catch the original bug
# tests 7
# suites 0
# pass 3
# fail 4
# cancelled 0
# skipped 0
# todo 0
Step 4: Confirm, then hand over
Participant:
Confirmed. Summarize the agreed decisions as acceptance criteria, then use /systematic-debugging to reproduce the defect. Do not edit yet.
Illustrative checkpoint:
The decisions now match BRIEF.md, so later steps work from explicit criteria instead of guesses. Baseline is still 3/7: grilling changes the plan, not the code.
Source or artifact snapshot:
Evidence to keep

Loaded path: .github/skills/grilling
Questions asked and your answers
Agreed decisions as criteria
No files edited

Still 3/7. Next: debug.
Observed test summary:
ok 1 - existing cart behavior is preserved
not ok 2 - quantities are applied
not ok 3 - invalid cart lines are rejected
not ok 4 - safe integer cents are enforced
ok 5 - inputs are left untouched
ok 6 - public API and scope are preserved
not ok 7 - learner regressions catch the original bug
# tests 7
# suites 0
# pass 3
# fail 4
# cancelled 0
# skipped 0
# todo 0
Takeaway: Let the agent interview you until every decision is explicit, so it cannot fill the gaps with guesses.
Try it yourself: Lab 2: anti-slop skills. Set up first with the lab environment guide.